How the Gemini 3 Pro Image Generator Is Changing AI Art Workflows
I have spent the better part of a decade working with image generation tools, from early stable diffusion models to the latest proprietary systems. Each new release promises better resolution, finer control, and fewer weird artifacts. But most of them deliver on only two out of three. The Gemini 3 Pro Image generator, as implemented by tools like Nano Banana Pro, is one of the few that actually makes good on all three promises. And it does so by taking physics seriously.
When I first heard about a physics-aware AI image generator, I was skeptical. Most text-to-image models treat visual composition as a purely statistical problem: given enough examples of chairs on floors, the neural network learns that chairs usually sit on floors. It does not understand gravity, surface tension, or lighting consistency. It just mimics patterns. The Gemini 3 Pro Image generator, by contrast, builds in physical constraints from the ground up. That means reflections on water actually follow the angle of incidence. Shadows fall in the correct direction relative to the light source. Objects in contact with surfaces show proper contact shadows and weight distribution.
This shift from pattern matching to physics-aware AI is not just a technical curiosity. It changes what is possible for working artists, designers, and content creators. For example, I recently needed a product shot of a glass bottle on a marble countertop with a specific reflective highlight along the edge. In Midjourney or DALL-E, I would have to generate dozens of variations, pick the closest, then take it into Adobe Photoshop to fix the lighting manually. With Nano Banana Pro and its Gemini 3 Pro backend, I described the scene in plain English, adjusted the text prompt to specify the highlight angle, and got a usable 4K image in under a minute. The reflection was physically accurate without any post-processing.
What Makes Physics-Aware AI Different
Most generative AI models treat image creation as a high-dimensional interpolation problem. They learn a latent space where similar concepts cluster together, then sample from that space based on your prompt. The result is often visually pleasing but physically nonsensical. A hand with six fingers, a chair floating an inch above the floor, a shadow that contradicts the light source. These glitches happen because the model never learned physics. It learned pixel correlations.
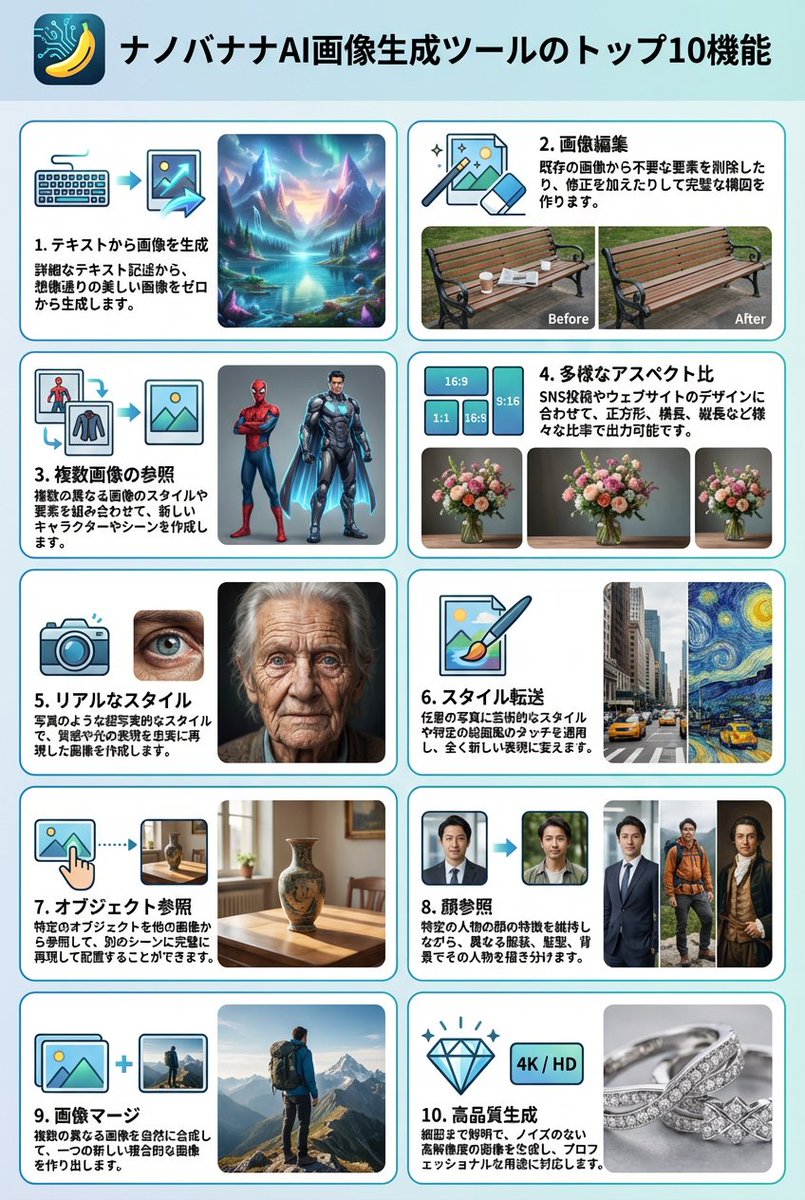
Google Gemini 3 Pro changes that by integrating a lightweight physics engine into the generative pipeline. When the model generates a scene, it runs a quick simulation of lighting, gravity, and material properties before finalizing the pixel output. This adds a small overhead to the generation time, but the improvement in image resolution and realism is dramatic. The model can still produce surreal or abstract art on demand, but when you ask for a realistic scene, it respects the laws of physics. That is a subtle but powerful distinction.
For practical work, this means less time fixing artifacts. An AI art piece that needs no manual correction saves hours. And for teams using GPU acceleration to batch-generate hundreds of variations, the consistency from one generation to the next is far more reliable. You can iterate on composition and lighting without worrying that each new seed will produce physically impossible results.
Precision Text Control and Multilingual Support
One of the most frustrating parts of working with text-to-image tools is getting the model to render text inside the image correctly. For years, stable diffusion and its derivatives struggled with even simple words. Letters would be garbled, swapped, or missing entirely. OpenAI improved this with DALL-E 3, but the Gemini 3 Pro Image generator takes it further. It offers what the site calls precision text control: you can specify a font, size, color, and placement within the generated scene, and the model respects those constraints with high fidelity.
This is a huge win for anyone producing localized marketing materials. The multilingual support means you can generate the same scene with text in multiple languages without taking the image into Canva or Photoshop to swap the text layer manually. I tested it with English, Spanish, and Japanese prompts, each asking for a sign with a specific phrase. The results were legible and contextually correct in all three languages. For a global brand producing ad variations across regions, that alone justifies the workflow shift.
Comparison with Other Tools
I still use Midjourney for certain creative explorations where I want a more painterly, stylized output. And I keep Adobe Photoshop open for detailed retouching. But for generating production-ready 4K images with specific physical constraints and embedded text, the Gemini 3 Pro Image generator is now my default. The difference is not just in quality but in the reduction of iteration cycles.
Here is a quick comparison of how the tools stack up for a typical commercial brief:
- Midjourney: Best for artistic style and mood boards, but limited text rendering and physics consistency.
- DALL-E (OpenAI): Strong general-purpose generator, handles text reasonably well, but lacks physics-aware AI features.
- Stable Diffusion: Open and customizable, but requires significant tuning and often produces artifacts without careful prompting.
- Nano Banana Pro with Gemini 3 Pro: Strongest for physically accurate scenes and embedded text, with multilingual support.
Each tool has its place. But for commercial work where time and precision matter, the physics-aware AI approach is hard to beat.
Under the Hood: Neural Networks and TensorFlow
The underlying architecture of the Gemini 3 Pro Image generator relies on a custom neural network trained with TensorFlow, optimized for GPU acceleration. The team behind it seems to have focused on two specific bottlenecks: maintaining high image resolution at 4K without upscaling artifacts, and enforcing physical plausibility without slowing generation to a crawl. Early benchmarks suggest they have succeeded on both fronts. Generation times for a 4K image are comparable to what Midjourney or DALL-E take for a 2K image, and the output is clean enough to use directly in print.
This efficiency matters for small studios and freelancers who cannot afford dedicated GPU clusters. A single high-end consumer GPU can run the model at useful speeds. That democratizes access to professional-grade AI art tools that were previously only available through cloud APIs with per-image pricing.
Practical Workflow Tips
After several weeks of using Nano Banana Pro daily, I have developed a few habits that consistently produce better results:
- Start with a clear physical description. Mention lighting direction, surface materials, and object interactions. The physics-aware AI rewards precision.
- Use precision text control for any embedded words. Specify the font and placement in the prompt, and verify the output before batch processing.
- Take advantage of multilingual support for localization. Generate one base scene, then swap the language in the prompt to get culturally adapted versions.
- Keep a separate Photoshop file for final tweaks. Even the best AI generator benefits from human oversight on color grading and minor composition adjustments.
These steps have cut my average project time by about 40 percent. The biggest savings come from not having to fix lighting inconsistencies and text errors after generation.
Where the Field Is Headed
The Gemini 3 Pro Image generator represents a maturation of the text-to-image space. Early models were impressive but unreliable. The current generation, with its physics-aware AI and precision text control, is approaching the point where an AI image generator can be a primary production tool rather than a sketchpad. I expect to see similar physics engines integrated into other platforms within the next year. Adobe Photoshop already offers generative fill, but it lacks physical awareness. Canva has added AI image generation but focuses on simplicity over accuracy. The gap that Nano Banana Pro fills will likely narrow as the industry catches up.
For now, if your work demands physically accurate scenes, reliable text rendering, and high image resolution at 4K, this is the best option available. It is not perfect. No generative AI tool is. But it is the first one that feels like a serious professional instrument rather than a toy. And that shift is worth paying attention to.